A topic sentence and an inclusion statement are enough to build a screened, mapped literature corpus
Literature grows faster than anyone can read it: by 2010, about seventy-five trials and eleven systematic reviews were published every day in medicine alone1. A systematic review registered in PROSPERO took a mean of 67 weeks to complete and publish, and only about 3% of the records its team screened ended up included2. Most of that effort goes to screening, and that is where tools have helped. Active learning ranks records so that reviewers see the relevant ones first3, and large language models now screen titles and abstracts directly: across six reviews and more than 24,000 records, one such screen reached 0.91 accuracy, with a sensitivity of 0.76 for the papers the reviewers included4, and accuracy fell when the inclusion criteria were narrow5. Both kinds of tool start from a search a person has already written and end in a ranked or filtered list.
The steps on either side of screening are still manual. Someone has to turn a question into database queries, follow the references of the key reviews, a method that can stand in for database search on its own6, merge what both return, and then work out how the surviving papers relate. veridian runs the whole loop from two inputs: a topic and an inclusion statement of two or three sentences. It drafts PubMed queries7, snowballs through the references and citing papers of a few seed reviews in OpenAlex8, screens every candidate against the inclusion statement with a one-line reason, and maps the included papers as a graph of citations, grouped and labeled with MeSH terms9, exported as CSV and BibTeX. Each run reports three numbers against targets set beforehand: precision, recall and wall time (Box 1). Nothing in the loop is specific to biomedicine except its sources: OpenAlex indexes every field, and the inclusion statement can describe any body of work. This write-up reports the first run of the loop, on a worked example.
Screening kept 1,199 of 3,205 candidates, and every sampled inclusion was in scope
Seven queries drafted from the topic returned 2,842 unique PubMed records, and snowballing from the four seeds returned 512 works. Merged, they gave 3,205 distinct candidate papers. The screen included 1,199, marked 383 maybe and excluded 1,623, each with a one-line reason. All 20 included papers drawn for the spot-check were in scope: precision 1.00 (95% CI 0.84–1.00), against a target of 0.80 (Table 1).
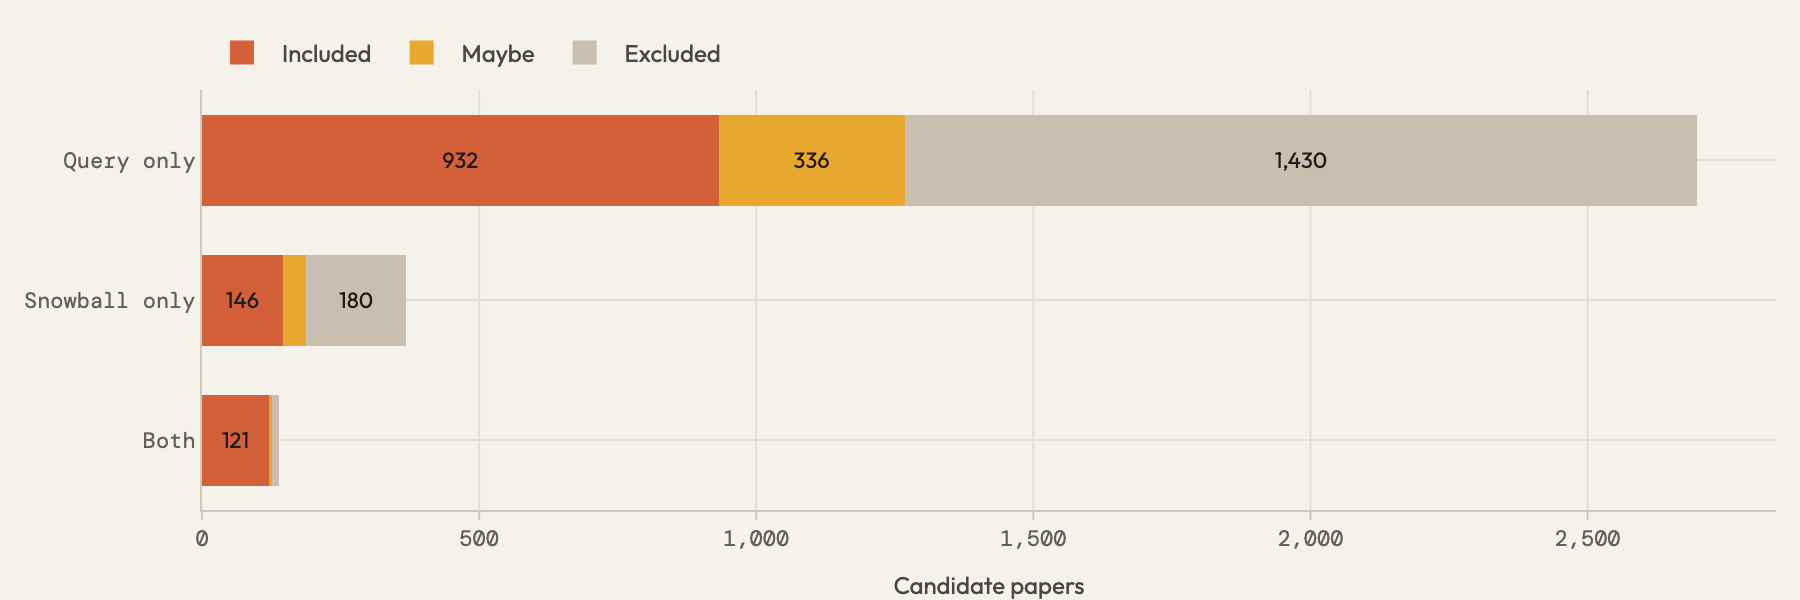
The two ways of finding papers did different work (Fig. 1). Of the 139 candidates found by both a query and a seed, 121 (87%) were included, against 932 of 2,698 (35%) found by queries alone. Snowballing alone contributed 146 included papers that no query retrieved, 12% of the included corpus. Queries supply the bulk of the corpus; the seeds' citation network marks its core and fills gaps the queries leave. The 395 candidates without an abstract were screened on their titles and were marked maybe more than twice as often as the rest (123, or 31%, against 12% overall), so the screen hedged where it had less to read rather than guessing.
An earlier corpus on hair, built from keyword queries alone with no screen, makes a useful backdrop, though not a matched comparison: its scope was narrower (chemical effects on the fiber) and its queries were fixed keyword strings. Only 6 of 48 sampled papers in it were in scope (12.5%, 95% CI 5.9–24.7%), and it failed its precision floor of 70%.
The included papers form four groups that are stable under resampling, but only just
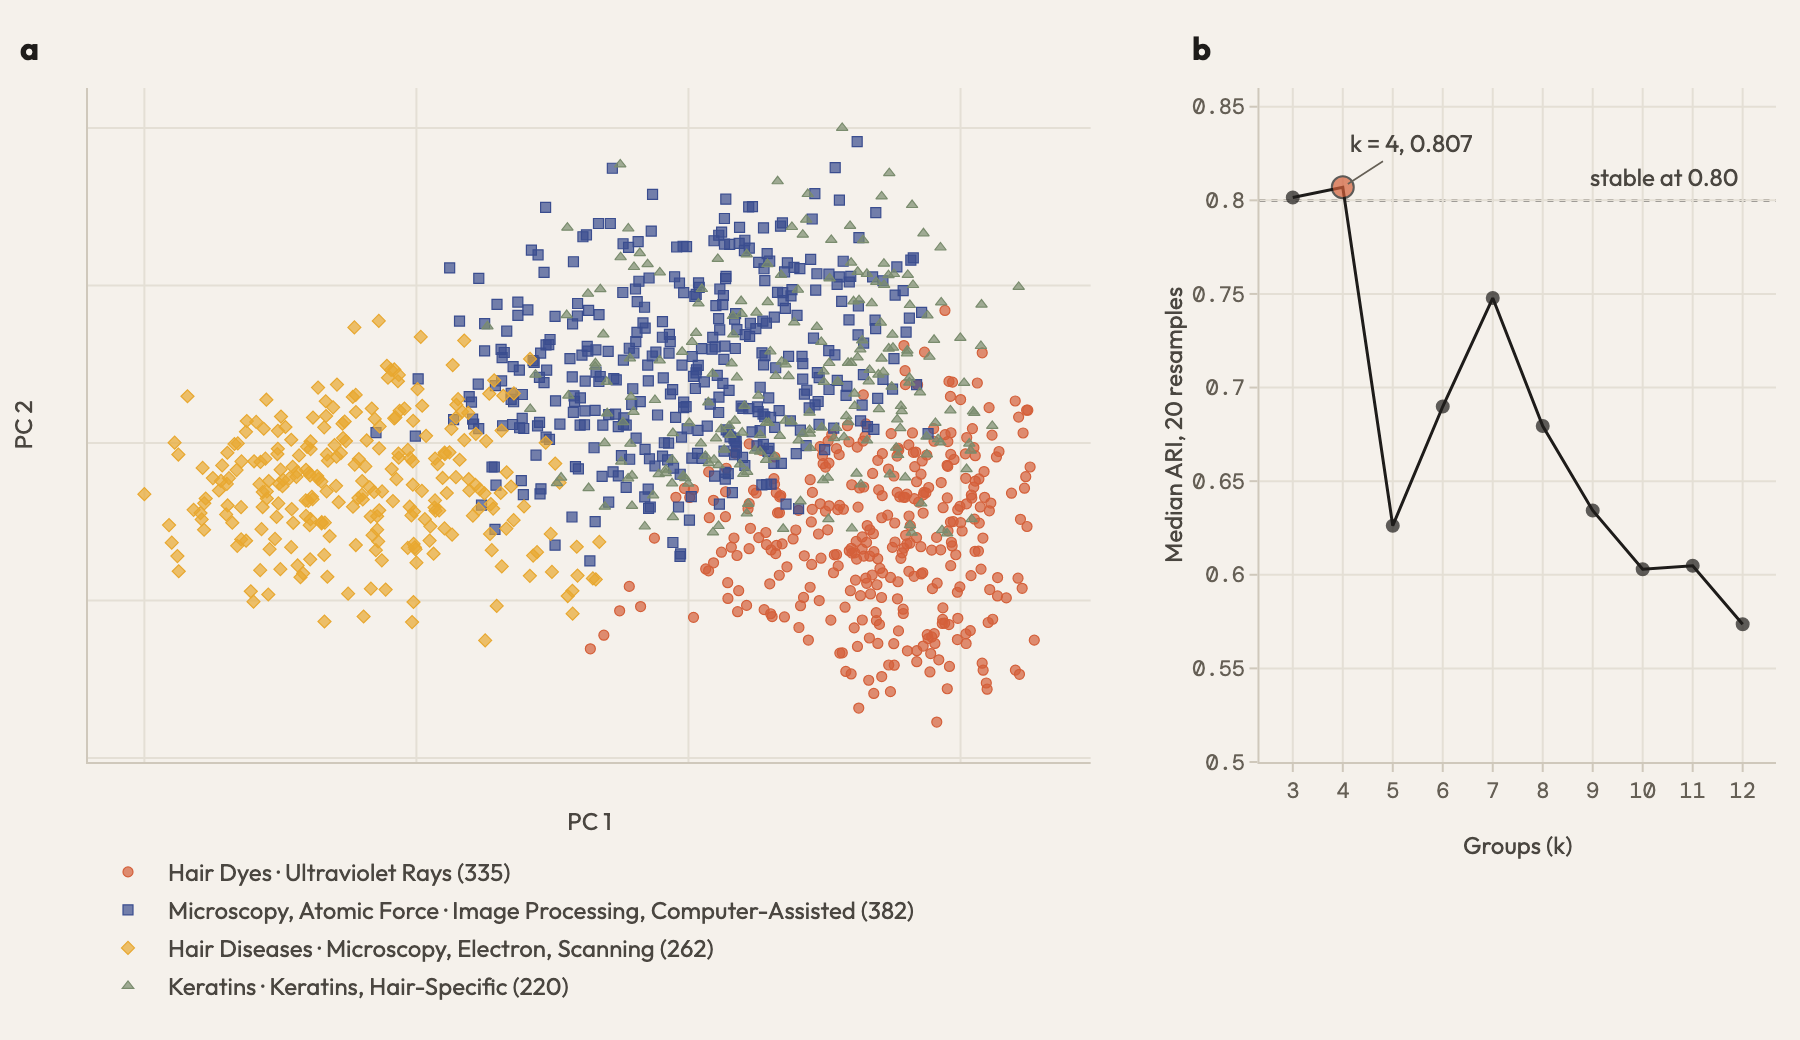
Grouping the 1,199 included papers by the text of their titles and abstracts, four groups reproduced themselves under resampling with a median ARI of 0.807, just above the 0.80 required (Fig. 2b). Three groups were as stable (0.802); every count from five to twelve fell short (0.574–0.748). Among the two stable counts, four had the higher silhouette (0.103 against 0.100). The groups are led by color, light and cosmetic treatment (335 papers; Hair Dyes, Ultraviolet Rays); imaging and mechanics of the fiber surface (382; Microscopy, Atomic Force, Image Processing, Computer-Assisted); hair-shaft disorders seen under the electron microscope (262; Hair Diseases, Microscopy, Electron, Scanning); and keratin structure (220; Keratins, Keratins, Hair-Specific) (Fig. 2a). The map links the papers by 6,019 citations among them; 1,006 of the 1,199 had reference lists in OpenAlex. The two journals that contributed most were cosmetic-science journals (J Cosmet Sci, 136 papers; Int J Cosmet Sci, 105).
The silhouette is low for every count tried (0.088–0.103), so the groups overlap: the map is better read as four regions of a continuous field than as four separate literatures.
Retrieval, not screening, limits recall
The corpus contained 20 of the 24 in-scope references of the recall review, and the screen included all 20: recall 0.83 (95% CI 0.64–0.93). None of the 24 was marked maybe or excluded. The four misses never reached the screen: no query returned them and no seed cited them or was cited by them. Three of the four compare hair across populations (eumelanin composition by ethnic origin, amino acid composition by racial origin, and the structure of ethnic skin and hair); the fourth describes normal cuticle wear. Because the recall review is itself about Asian hair, its references lean toward population comparisons, and recall measured against it tests that slice of the field more than the rest.
A count made after seeing these misses, and labeled post hoc for that reason, shows that the screen does not lose work on different hair types. Of the 217 candidates indexed with any ancestry or population heading, 123 were included (57%, against 37% for all candidates); of the 63 that describe Afro-textured hair in their title or abstract, 32 were included (51%). These papers are scarce in what retrieval brings back: the Afro-textured ones make up 2.7% of the included corpus, and those with an African-ancestry heading 3.1%. Some seeds were chosen for their attention to hair-type diversity12, so they probably pull in more of this work than queries alone would; the true gap in coverage is likely larger than these shares suggest. These counts appear only here: ancestry and country terms are never used to label the map.
| Measure | Target | Result | Met |
|---|---|---|---|
| Precision | ≥ 0.80 | 1.00 (95% CI 0.84–1.00), 20 of 20 | Yes |
| Wall time, topic to map | < 15 min | 5.7 mina | Yes |
| Map stability | Median ARI ≥ 0.80 | 0.807 at four groups | Yes |
| Recall | None set | 0.83 (95% CI 0.64–0.93), 20 of 24b | — |
a Snowball 0.2 s, queries 32.5 s, merge 1.2 s, screen 258.8 s, map 49.4 s. Snowball and merge were timed from cache, so a cold run takes longer by the time the OpenAlex requests take. b All four misses were never retrieved; recall is reported without a target, by design.
Discussion
From a one-line topic and a one-sentence inclusion statement, veridian built a corpus of 1,199 papers on human hair fiber science in under six minutes of step time, every sampled inclusion was in scope, and the included papers fell into four groups stable enough to map. The screen is not the weak point: it included every in-scope reference it was shown, and it included papers on different hair types at a higher rate than papers overall. What it was never shown is the limit. Recall is bounded by retrieval, and the papers retrieval missed were mostly the ones that compare hair across populations.
Several caveats bound these numbers. Precision rests on 20 papers judged by one reader, the author, and its interval runs down to 0.84. Six of the 20 were first set aside as hard to judge from the abstract; four were then judged in scope on a second reading and two were approved without one. Had those two been out of scope, precision would have been 0.90, still above target. Recall rests on 24 references from one review whose subject tilts it toward population comparisons, so its interval is wide (0.64–0.93) and it says little about the rest of the field. The wall time was measured on a run whose snowball and merge steps were read from cache; the screen and the map, which take 308 of the 342 seconds, ran live, but a cold run was not timed. The four groups only just clear the stability bar, and a stable clustering is not proof of a true one20; their low silhouette means the boundaries between them are soft. The screen itself has not been compared with a second human screener, though human screeners disagree substantially with one another too4. And this is one run, on one topic.
The next test is a topic outside biomedicine, where PubMed cannot help and OpenAlex must carry retrieval alone, with its targets committed before it runs. A query facet for cross-population comparisons would likely recover the papers this run missed, but adding it after seeing the misses would be tuning to the recall review; it belongs in the inputs of a new run, not in a rescoring of this one.
Methods
Inputs. A run is a short text file: a topic, an inclusion statement, PubMed IDs for the seed reviews, the recall review and a precision target. For the hair run, three seeds contributed their references and the papers citing them10,12,13, and one, whose references reach into animal fibers, contributed citing papers only11.
Queries. A language model (Claude Opus 5.5) drafted seven faceted PubMed queries from the topic and the inclusion statement, combining MeSH headings with title and abstract terms. Each query returned at most 500 records through NCBI's E-utilities7; together they gave 2,842 unique PMIDs.
Snowballing. For each seed, OpenAlex8 supplied its reference list and the works citing it, 512 works in all. Requests carried no personal contact details.
Merge. The 6,075 records from both channels were joined into one record per paper on PMID, then DOI, then OpenAlex ID, and as a last resort on a normalized title within two years, which is how a preprint meets its journal version; two different PMIDs were never joined. The record with a PMID wins, because PubMed carries the abstract and MeSH indexing. Of the 3,205 papers, 3,011 matched an OpenAlex work and 395 had no abstract.
Screen. Claude Haiku 5.5, without extended thinking, read titles and abstracts in batches of 20, eight batches at a time, and returned include, maybe or exclude with a one-line reason for each paper. The 161 calls all succeeded and used 2.0 million tokens. The prompt and inclusion statement are hashed into the output (prompt f2c9e091b91e7351, inclusion statement 82c3683d62fb58ed), so a rerun with either changed cannot reuse cached decisions. Papers about animal fibers alone were excluded unless they also studied human hair or modeled keratin-fiber structure that applies to it.
Map. Each included paper's title and abstract were embedded with MiniLM-L6-v2 sentence embeddings21,22 (ONNX, 8-bit). For each number of groups from 3 to 12, k-means was refit on 20 random draws of 80% of the papers, and stability was the median adjusted Rand index18 between refits on the papers they shared16,17. Among counts with a median of at least 0.80, the one with the highest cosine silhouette19 was chosen. The layout is the first two principal components. Each group is labeled by the two MeSH major headings9 most over-represented in it relative to the corpus; ancestry and country headings are never used as labels. Edges are citations between included papers, from OpenAlex reference lists.
Run report. Precision: 20 included papers drawn at random with the run name as seed, so the draw is the same every time, judged by the author against the inclusion statement from title and abstract. Recall: the author labeled all 76 references of the recall review14 before scoring; 24 study the fiber itself and are in scope, while its references on scalp disorders, the genetics of hair form, assay methods and hair growth are not. A reference counts as found when its PMID or OpenAlex ID belongs to an included paper. Intervals are 95% Wilson intervals15. Wall time is the sum of each step's latest recorded time.
Coverage count (post hoc). Candidates were counted by MeSH ancestry and population headings, by African-ancestry headings, and by Afro-textured wording in the title or abstract, after the recall misses were seen.
Keyword baseline. The earlier corpus held 1,520 PubMed records from eight fixed keyword strata on chemical effects on the fiber. Of 50 abstracts drawn for its precision read, 33 plainly out of scope were set aside by a language model with a reason each, a logged deviation; the author judged the rest and left 2 undecided, giving 6 of 48.
Data availability
Records come from PubMed through NCBI's E-utilities7 and from OpenAlex8, both public. The run's candidates, screen decisions with their reasons, map, recall labels and spot-check decisions are committed to the project repository. The data behind each figure ships with this page as a table.
Code availability
The analysis repository is private.
Pre-registration statement
Pre-registered means committed to the project's own repository before scoring, not lodged with an external registry. The precision target, the wall-time target, the seeds and the recall review were committed on 16 October 2026 before the run; recall was deliberately given no target. One change was made after the screen had run and before precision was scored: papers about animal fibers alone were excluded, which left recall unchanged. The precision spot-check's handling of hard-to-judge papers is described in the Discussion. The coverage count is post hoc. An earlier protocol for a hair corpus, pre-registered on 15 October 2026, was retired when the project was reset to the loop reported here; its keyword corpus failed its precision floor and is reported above as context.
Competing interests
None.
References
- Bastian H, Glasziou P, Chalmers I. Seventy-Five Trials and Eleven Systematic Reviews a Day: How Will We Ever Keep Up? PLoS Medicine 7, e1000326 (2010). doi:10.1371/journal.pmed.1000326.
- Borah R, Brown AW, Capers PL, Kaiser KA. Analysis of the time and workers needed to conduct systematic reviews of medical interventions using data from the PROSPERO registry. BMJ Open 7, e012545 (2017). doi:10.1136/bmjopen-2016-012545.
- van de Schoot R, de Bruin J, Schram R, et al. An open source machine learning framework for efficient and transparent systematic reviews. Nature Machine Intelligence 3, 125–133 (2021). doi:10.1038/s42256-020-00287-7.
- Guo E, Gupta M, Deng J, Park YJ, Paget M, Naugler C. Automated Paper Screening for Clinical Reviews Using Large Language Models: Data Analysis Study. Journal of Medical Internet Research 26, e48996 (2024). doi:10.2196/48996.
- Ramchandani R, Guo E, Mostowy M, et al. Validation of automated paper screening for esophagectomy systematic review using large language models. PeerJ Computer Science 11, e2822 (2025). doi:10.7717/peerj-cs.2822.
- Wohlin C. Guidelines for snowballing in systematic literature studies and a replication in software engineering. Proceedings of the 18th International Conference on Evaluation and Assessment in Software Engineering (EASE '14), 38:1–38:10 (2014). doi:10.1145/2601248.2601268.
- Sayers EW, Bolton EE, Brister JR, et al. Database resources of the National Center for Biotechnology Information. Nucleic Acids Research 50, D20–D26 (2022). doi:10.1093/nar/gkab1112.
- Priem J, Piwowar H, Orr R. OpenAlex: A fully-open index of scholarly works, authors, venues, institutions, and concepts. arXiv 2205.01833 (2022). arXiv:2205.01833.
- Lipscomb CE. Medical Subject Headings (MeSH). Bulletin of the Medical Library Association 88, 265–266 (2000). PMID:10928714.
- Cloete E, Khumalo NP, Van Wyk JC, Ngoepe MN. Systems Approach to Human Hair Fibers: Interdependence Between Physical, Mechanical, Biochemical and Geometric Properties of Natural Healthy Hair. Frontiers in Physiology 10, 112 (2019). doi:10.3389/fphys.2019.00112.
- Popescu C, Höcker H. Hair—the most sophisticated biological composite material. Chemical Society Reviews 36, 1282–1291 (2007). doi:10.1039/b604537p.
- Daniels G, Fraser A, Westgate GE. How different is human hair? A critical appraisal of the reported differences in global hair fibre characteristics and properties towards defining a more relevant framework for hair type classification. International Journal of Cosmetic Science 45, 50–61 (2023). doi:10.1111/ics.12819.
- Csuka DA, Csuka EA, Juhász MLW, Sharma AN, Mesinkovska NA. A systematic review on the lipid composition of human hair. International Journal of Dermatology 62, 404–415 (2023). doi:10.1111/ijd.16109.
- Leerunyakul K, Suchonwanit P. Asian Hair: A Review of Structures, Properties, and Distinctive Disorders. Clinical, Cosmetic and Investigational Dermatology 13, 309–318 (2020). doi:10.2147/CCID.S247390.
- Wilson EB. Probable Inference, the Law of Succession, and Statistical Inference. Journal of the American Statistical Association 22, 209–212 (1927). doi:10.1080/01621459.1927.10502953.
- Ben-Hur A, Elisseeff A, Guyon I. A stability based method for discovering structure in clustered data. Pacific Symposium on Biocomputing, 6–17 (2002). PMID:11928511.
- Lange T, Roth V, Braun ML, et al. Stability-Based Validation of Clustering Solutions. Neural Computation 16, 1299–1323 (2004). doi:10.1162/089976604773717621.
- Hubert L, Arabie P. Comparing partitions. Journal of Classification 2, 193–218 (1985). doi:10.1007/BF01908075.
- Rousseeuw PJ. Silhouettes: A graphical aid to the interpretation and validation of cluster analysis. Journal of Computational and Applied Mathematics 20, 53–65 (1987). doi:10.1016/0377-0427(87)90125-7.
- Ben-David S, von Luxburg U, Pál D. A Sober Look at Clustering Stability. Learning Theory (COLT), LNCS 4005, 5–19 (2006). doi:10.1007/11776420_4.
- Reimers N, Gurevych I. Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks. Proceedings of EMNLP-IJCNLP, 3980–3990 (2019). doi:10.18653/v1/D19-1410.
- Wang W, Wei F, Dong L, et al. MiniLM: Deep Self-Attention Distillation for Task-Agnostic Compression of Pre-Trained Transformers. arXiv 2002.10957 (2020). arXiv:2002.10957.